AAAI 2024Temporal knowledge editing
History Matters: Temporal Knowledge Editing in Large Language Model
Updating a model with today's facts can erase yesterday's answers; METO edits current and historical knowledge together so that facts remain associated with their time periods.
- Result
- On AToKe single edits with GPT-J, METO raises MEMIT's historical explicit-time accuracy (HES) from 2.22% to 30.31%, while current accuracy (CES) falls from 99.66% to 86.4%.
- New vs prior
- ROME, MEMIT, and MEND optimize only the new fact, and evaluations such as MQuAKE check related facts; this work also requires the replaced fact to survive as dated history.
- Limitation
- Historical recall stays incomplete: after multiple edits the best final historical score (HES*) is 21.93%, and METO lowers MEMIT's current explicit-time accuracy by 13.26 points.
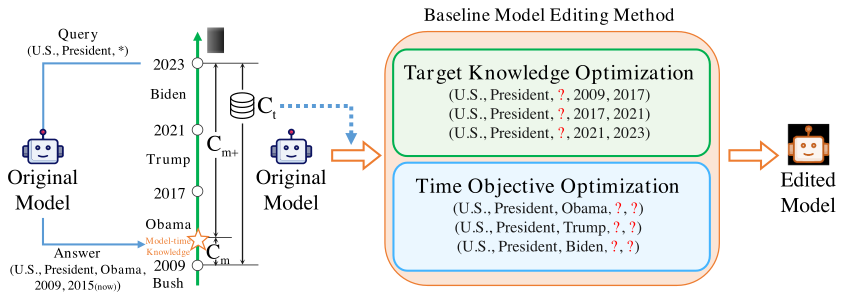
An update should not erase the past
Correcting a false fact and updating a once-true fact are different operations: when a leader changes, the old and new answers are both correct for different dates. The paper calls the second case Temporal Knowledge Editing (TKE). An editor can pass tests on the new answer, its paraphrases, and unrelated facts while erasing the earlier one, because locality tests do not check the edited fact's history.
The new benchmark, AToKe (Assessment of TempOral Knowledge Editing), asks explicit-time questions, such as who held a position in a given span, and relative-time questions, such as who held it previously. The latter require an ordered history rather than isolated date–answer pairs.
Closest prior work
Existing editors, from constrained fine-tuning and MEND to ROME and MEMIT, are built to make the model memorize the new fact, and their evaluations check edit success, paraphrases, and unrelated neighborhood facts. MQuAKE (Zhong et al., 2023) adds multi-hop questions about facts related to an edit, and Cohen et al. (2023) measure ripple effects. The paper argues that none of these checks whether the pre-edit fact is preserved as history, which is the requirement Temporal Knowledge Editing adds.
METO recovers some history at a cost to current accuracy
2.22 → 30.31
Historical score (%)
On AToKe single edits, METO raises MEMIT's accuracy on questions with explicit historical dates by 28.09 percentage points.
99.66 → 86.4
Current score (%)
Current explicit-time accuracy for the same edits. The cost depends on the editor: METO changes it by −13.26 points for MEMIT, −0.04 for ROME, and +2.79 for MEND.
Measured · Tables 2–3, GPT-J 6B
Which question forms does METO recover?
Choose an edit sequence, a question form, and an editor to compare measured accuracy without METO (Table 2) and with it (Table 3). All four editors stay visible for the chosen form.
Measured accuracy on HES* (Every historical fact, explicit time), GPT-J, multiple edits
Without METO (Table 2)With METO (Table 3)
- CFT0.01 → 0.73+0.71
- MEND0.25 → 21.83+21.58
- ROME0.26 → 15.92+15.66
- MEMIT0.27 → 21.93+21.66
Selected cell
MEMIT · HES* · multiple edits: 0.27% without METO → 21.93% with METO (+21.66 points). Without METO, historical probes almost never succeed; with METO, 21.93% do. Over the same edits, CES moves from 98.42% to 92.73%.
Change with METO across every question form
Percentage points as printed in Table 3, multiple edits. The selected form and editor are outlined.
| Question form | CFT | MEND | ROME | MEMIT |
|---|---|---|---|---|
| CESCurrent fact, explicit time | +0.16 | −1.31 | +1.08 | −5.69 |
| CES-PCurrent fact, explicit time, paraphrased | +0.02 | +0.45 | −0.57 | −5.31 |
| CRSCurrent fact, relative time | −0.18 | −1.83 | +5.32 | +7.10 |
| HESHistorical fact, explicit time | +1.61 | +28.25 | +22.78 | +35.72 |
| HRSHistorical fact, relative time | +1.23 | +28.73 | +17.01 | +25.18 |
| HES*Every historical fact, explicit time | +0.71 | +21.58 | +15.66 | +21.66 |
Measured: Table 2 (existing editors) and Table 3 (with METO), GPT-J 6B on AToKe; changes are those printed in Table 3. The multiple-edit scores average each edit of a chain; HES* is asked once after the final edit. The probes behind each form are shown for one record in Method.
Without METO, every editor nearly erases history: single-edit HES is at most 2.41%, and HES* after multiple edits at most 0.27%. With METO, HES* exceeds 15% for every editor except CFT. Retention is not free: under single edits, METO lowers paraphrased (CES-P) and relative-time (CRS) current accuracy for all four editors.
Two difficulty patterns hold with and without METO: relative-time questions are harder than explicit-time ones, likely because they require ordering facts rather than recalling dates, and repeated edits are harder than a single one.
Scope. The main experiments edit GPT-J on timestamped fact chains. Historical recall improves substantially but remains incomplete, and improvements need to be assessed alongside accuracy on current facts. Read the study ↗
Read the abstract
The imperative task of revising or updating the knowledge stored within large language models arises from two distinct sources: intrinsic errors inherent in the model which should be corrected and outdated knowledge due to external shifts in the real world which should be updated. Prevailing efforts in model editing conflate these two distinct categories of edits arising from distinct reasons and directly modify the original knowledge in models into new knowledge. However, we argue that preserving the model's original knowledge remains pertinent. Specifically, if a model's knowledge becomes outdated due to evolving worldly dynamics, it should retain recollection of the historical knowledge while integrating the newfound knowledge. In this work, we introduce the task of Temporal Knowledge Editing (TKE) and establish a benchmark AToKe (Assessment of TempOral Knowledge Editing) to evaluate current model editing methods. We find that while existing model editing methods are effective at making models remember new knowledge, the edited model catastrophically forgets historical knowledge. To address this gap, we propose a simple and general framework termed Multi-Editing with Time Objective (METO) for enhancing existing editing models, which edits both historical and new knowledge concurrently and optimizes the model's prediction for the time of each fact. Our assessments demonstrate that while AToKe is still difficult, METO maintains the effectiveness of learning new knowledge and meanwhile substantially improves the performance of edited models on utilizing historical knowledge.
Full paper ↗Citation BibTeX
@inproceedings{yin2024history,
  title={History matters: Temporal knowledge editing in large language model},
  author={Yin, Xunjian and Jiang, Jin and Yang, Liming and Wan, Xiaojun},
  booktitle={Proceedings of the AAAI Conference on Artificial Intelligence},
  volume={38},
  number={17},
  pages={19413--19421},
  year={2024}
}